Harmonic oscillator
The quickstart. One unknown with a known answer, the angular frequency HybridModel workflow: build a dataset, fit, read the result, predict, simulate new conditions. Read it first, and come back to it when you want to check that your own data, ODE and training path are wired correctly.
Run it
uv run python examples/pendulum/train_harmonic.py
uv run python examples/pendulum/train_harmonic.py --no-plot
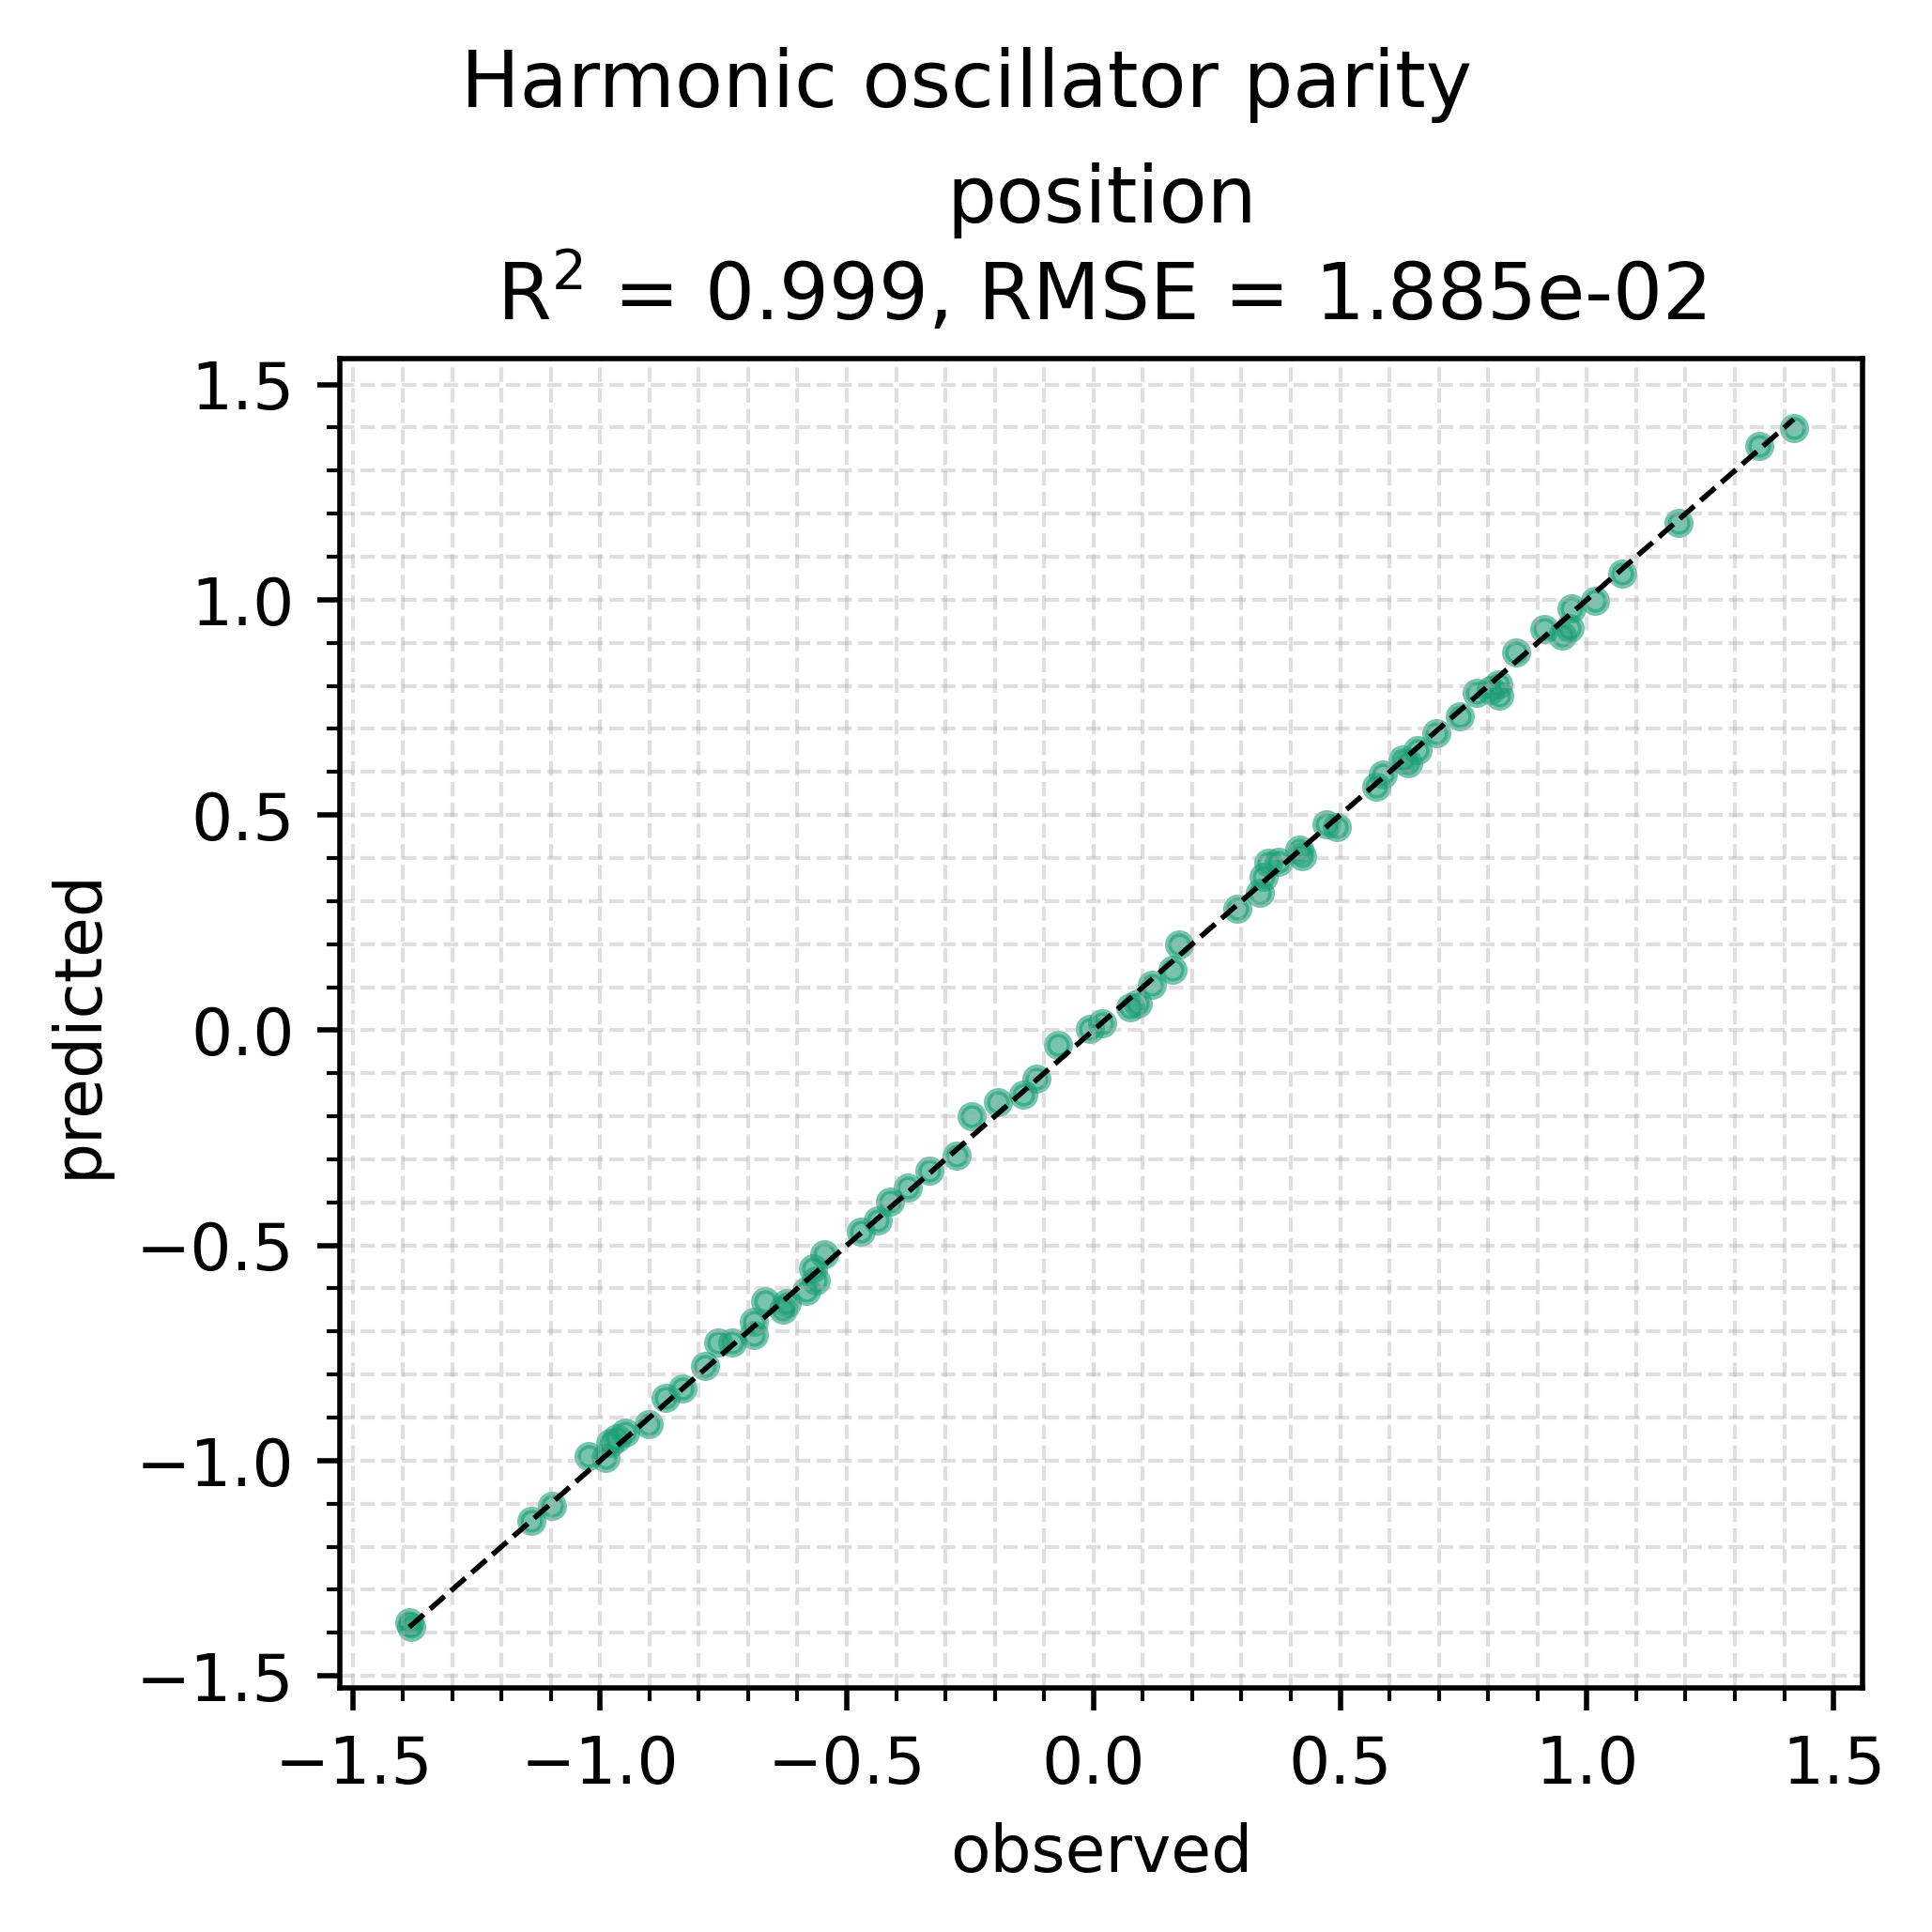
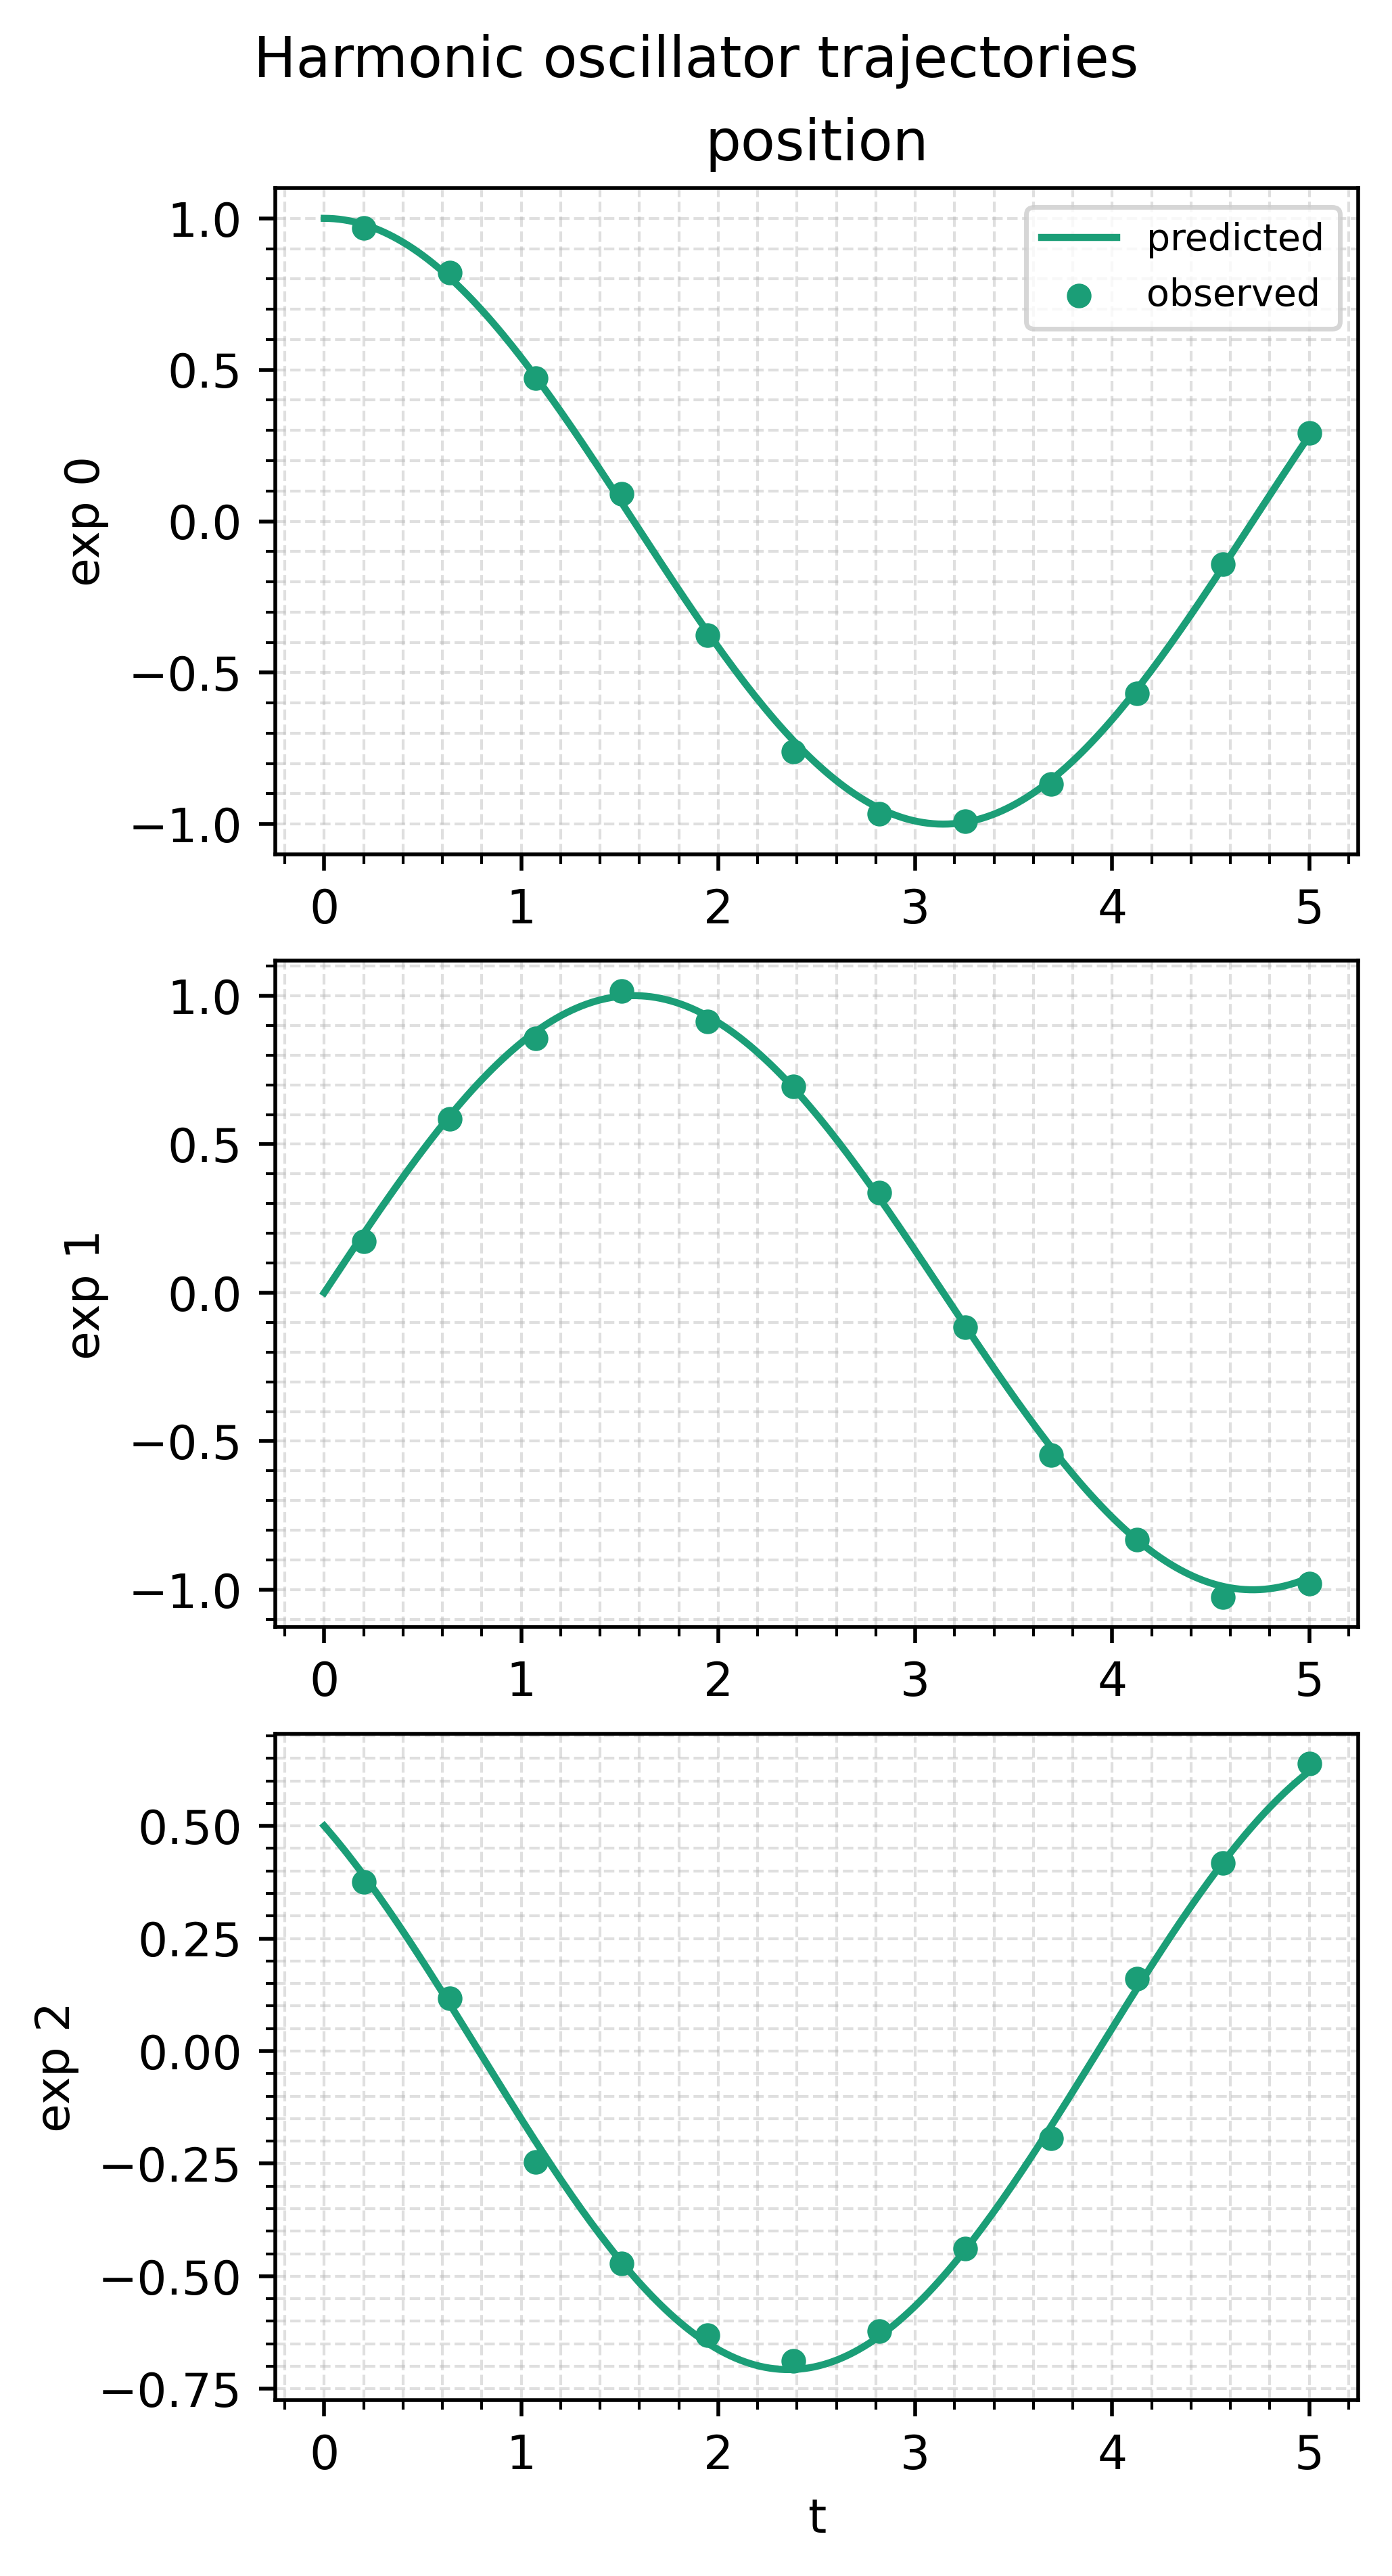
About 15 s on CPU. The data is generated on every run. Writes figures/parity.png and figures/trajectories.png next to the script unless --no-plot is given.
The model
Code
The model is one ODE solve, so the script writes only the vector field. The predictors arrive as the dict given to the model, and both kinds of value are read through .value. state_to_output keeps the measured column:
def vector_field(
    t: ArrayLike,
    y: Float[Array, " 2"],
    predictors: dict[str, hm.Parameter | hm.Constant],
    covariates: dict[str, Array],
) -> Float[Array, " 2"]:
    """``d[x, v]/dt`` for one oscillator. Both predictor kinds are read through ``.value``."""
    omega = predictors["omega"].value
    damping = predictors["damping"].value
    return jnp.stack([y[1], -(omega**2) * y[0] - damping * y[1]])


def state_to_output(state: Float[Array, "T 2"]) -> Float[Array, "T 1"]:
    """Only position is observed."""
    return state[..., :1]
Each experiment gives its initial state at t0, before the first measurement. Use y0_fn= instead of y0= when the state has to be computed from covariates or from the first observation:
hm.make_experiment(
    channels={"position": hm.ChannelObs(ts=TS, values=noisy, variance=NOISE_STD**2)},
    # The state is known at t0 = 0; the first measurement is at 0.2.
    t0=0.0,
    y0=[x0, v0],
    exp_id=f"osc_{i}",
)
HybridModel.from_vector_field wraps the vector field into a simulate_fn that integrates one experiment and returns the full state. Write simulate_fn yourself when a model needs more than one plain solve, as the hybrid ODE does. SolverConfig() defaults to Tsit5 with rtol=1e-5 and atol=1e-7; only the first step size is set here. A Parameter trains on an unbounded latent and maps it into its bounds, so Constant is never trained:
model = hm.HybridModel.from_vector_field(
    vector_field=vector_field,
    predictors={
        # Trained, and kept inside (0.5, 2.0) at every step.
        "omega": hm.Parameter(OMEGA_INIT, bounds=(0.5, 2.0)),
        # Known and fixed: the default training mask never updates it.
        "damping": hm.Constant(0.0),
    },
    state_to_output=state_to_output,
    output_channel_names=CHANNELS,
    # Tsit5 with rtol 1e-5 and atol 1e-7 by default; only the first
    # step size differs here.
    solver=hm.SolverConfig(dt0=0.05),
)
Training runs two phases, a fast one to get close and a slower one to settle. fit returns a FitResult; result.model is a new model with the fitted values and model is unchanged:
config = hm.OptaxTrainingConfig(
    phases=(
        hm.TrainingPhase(steps=200, lr=0.05),
        hm.TrainingPhase(steps=100, lr=0.01),
    ),
    verbose=False,
)
result = model.fit(dataset, config, key=k_train)
predict runs the fitted model on each experiment's times and is indexed by experiment, then channel. Its times start at t0, where nothing was measured. simulate needs no dataset, only times, an initial state and any covariates the model reads:
predictions = result.model.predict(dataset)
# Indexed by experiment, then channel. ``times`` starts at t0, where
# nothing was measured.
first = predictions["osc_0"]
print(
    f"osc_0 at t = {float(first.times[1]):.2f}: x = {float(first.outputs['position'][1]):.4f}"
)
# A new oscillator, run past the end of the training window.
new = result.model.simulate(ts=jnp.linspace(0.5, 10.0, 50), t0=0.0, y0=[0.5, 0.0])
print(f"new oscillator at t = 10: x = {float(new.outputs['position'][-1]):.4f}")
Results
[fit]
omega 1.4 -> 0.9997 (true 1.0)
best step 186, stop reason budget_exhausted

  channel           n           MSE          RMSE           MAE      R^2
  position         72    3.5542e-04    1.8853e-02    1.5612e-02   0.9993
The MSE sits at the noise variance, best_step is the step whose parameters were returned, and budget_exhausted means training ran all its steps without stopping early.
Things to try
- Make the damping trainable,
hm.Parameter(0.1, bounds=(0.0, 1.0)), and startfrom 1.9. With two unknowns and a far start, the same 300 steps reach instead of 1.000, and best_stepis the last step: the run needs more steps, not a different model. - If
comes out more than about 1% from 1.0 after you adapt this script, look first at state_to_outputand the initial states.