Crystallisation (mechanistic)
The parametric baseline for the hybrid crystallisation example. Same data, moment ODE and observation model; the two rate networks are replaced by closed-form kinetics with four fitted constants, searched with CMA-ES. Use it as a template for fitting a handful of bounded physical constants without gradients, and as the number a hybrid model has to beat.
Run it
uv run python examples/crystallisation/train_crystallisation_mechanistic.py
uv run python examples/crystallisation/train_crystallisation_mechanistic.py \
    --generations 2 --population-size 8 --no-plot   # smoke check
The default runs 80 generations of 64 candidates, under a minute on CPU. It prints the four constants before and after the fit and per-channel metrics, and writes parity_mechanistic.png and trajectories_mechanistic.png to examples/crystallisation/figures/.
The model
The dataset, the moment equations and state_to_output are imported from train_kinetic.py; the hybrid page describes them. Only the rate laws differ. Nucleation follows classical nucleation theory (CNT) and growth a power law in
| name | meaning | bounds |
|---|---|---|
logA | (20.0, 65.0) | |
gamma | interfacial energy [mJ/m²] | (0.15, 1.0) |
Ag | (-20.0, -5.0) | |
g | growth exponent | (1.0, 3.5) |
The bounds come from the thesis package, so the fitted values are comparable with its runs. All four constants are shared by every experiment; temperature enters only through CNT and the solubility.
Code
Each constant is a Parameter that starts at the midpoint of its bounds:
model = hm.HybridModel(
    predictors={
        name: hm.Parameter((low + high) / 2, bounds=(low, high))
        for name, (low, high) in PARAMETER_BOUNDS.items()
    },
    simulate_fn=simulate_fn,
    state_to_output=state_to_output,
    output_channel_names=OUTPUT_CHANNELS,
    solver=SOLVER,
)
A Parameter stores an unbounded latent and returns its bounded physical value from .value. CMA-ES searches the latents, so every candidate maps inside the box and the search needs no constraint handling. The constants are read once per solve, outside the vector field:
def vector_field(t: ArrayLike, y: Float[Array, " 6"], args: object) -> Float[Array, " 6"]:
    S = y[5] / conc_sat
    meta_mask = (S > 1.0 + META_EPS).astype(y.dtype)

    # Keep S just above 1 inside the log. The mask already zeros the
    # rate below saturation, but ln(1) = 0 in the denominator would
    # still put a nan into the gradient of every step.
    S_safe = jnp.clip(S, min=1.0 + 1e-12)
    cnt_exponent = (
        -16.0 * jnp.pi * gamma**3 * M_V**2 / (3.0 * (K_B * T_K) ** 3 * jnp.log(S_safe) ** 2)
    )
    J = meta_mask * jnp.exp(logA) * S_safe * jnp.exp(cnt_exponent)

    # Ag is per minute, as in the thesis package; /60 gives per second.
    G = meta_mask * 10.0**Ag / 60.0 * jnp.maximum(S - 1.0, 0.0) ** g
    return moment_rhs(y, G, J)
Passing an EvosaxTrainingConfig to fit selects the evolutionary trainer:
config = hm.EvosaxTrainingConfig(
    algorithm="CMA_ES",
    population_size=args.population_size,
    steps=args.generations,
    init=args.init,
    init_box_extent=args.init_box_extent,
    sigma_init=args.sigma_init,
)
init="lhs_box" fills generation 0 with a Latin hypercube over the latent box, and each generation is one compiled, vmapped evaluation of the whole population. CNT makes the ODE stiff for many candidates, so this script uses the implicit Kvaerno3 solver. result.history.loss holds the best loss so far at each generation, so it never increases.
Results
Seed 0, 80 generations of 64:
| constant | init | fitted |
|---|---|---|
logA | 42.50 | 26.03 |
gamma | 0.575 | 0.444 |
Ag | -12.50 | -9.14 |
g | 2.250 | 3.198 |
Against the hybrid model on the same data, from the default run of train_kinetic.py:
| model | trained | best loss | conc | d43 |
|---|---|---|---|---|
| hybrid, two MLPs | 600 Adam steps | 0.274 | 0.970 | 0.983 |
| mechanistic, 4 constants | 80 × 64 CMA-ES | 1.230 | 0.884 | 0.404 |
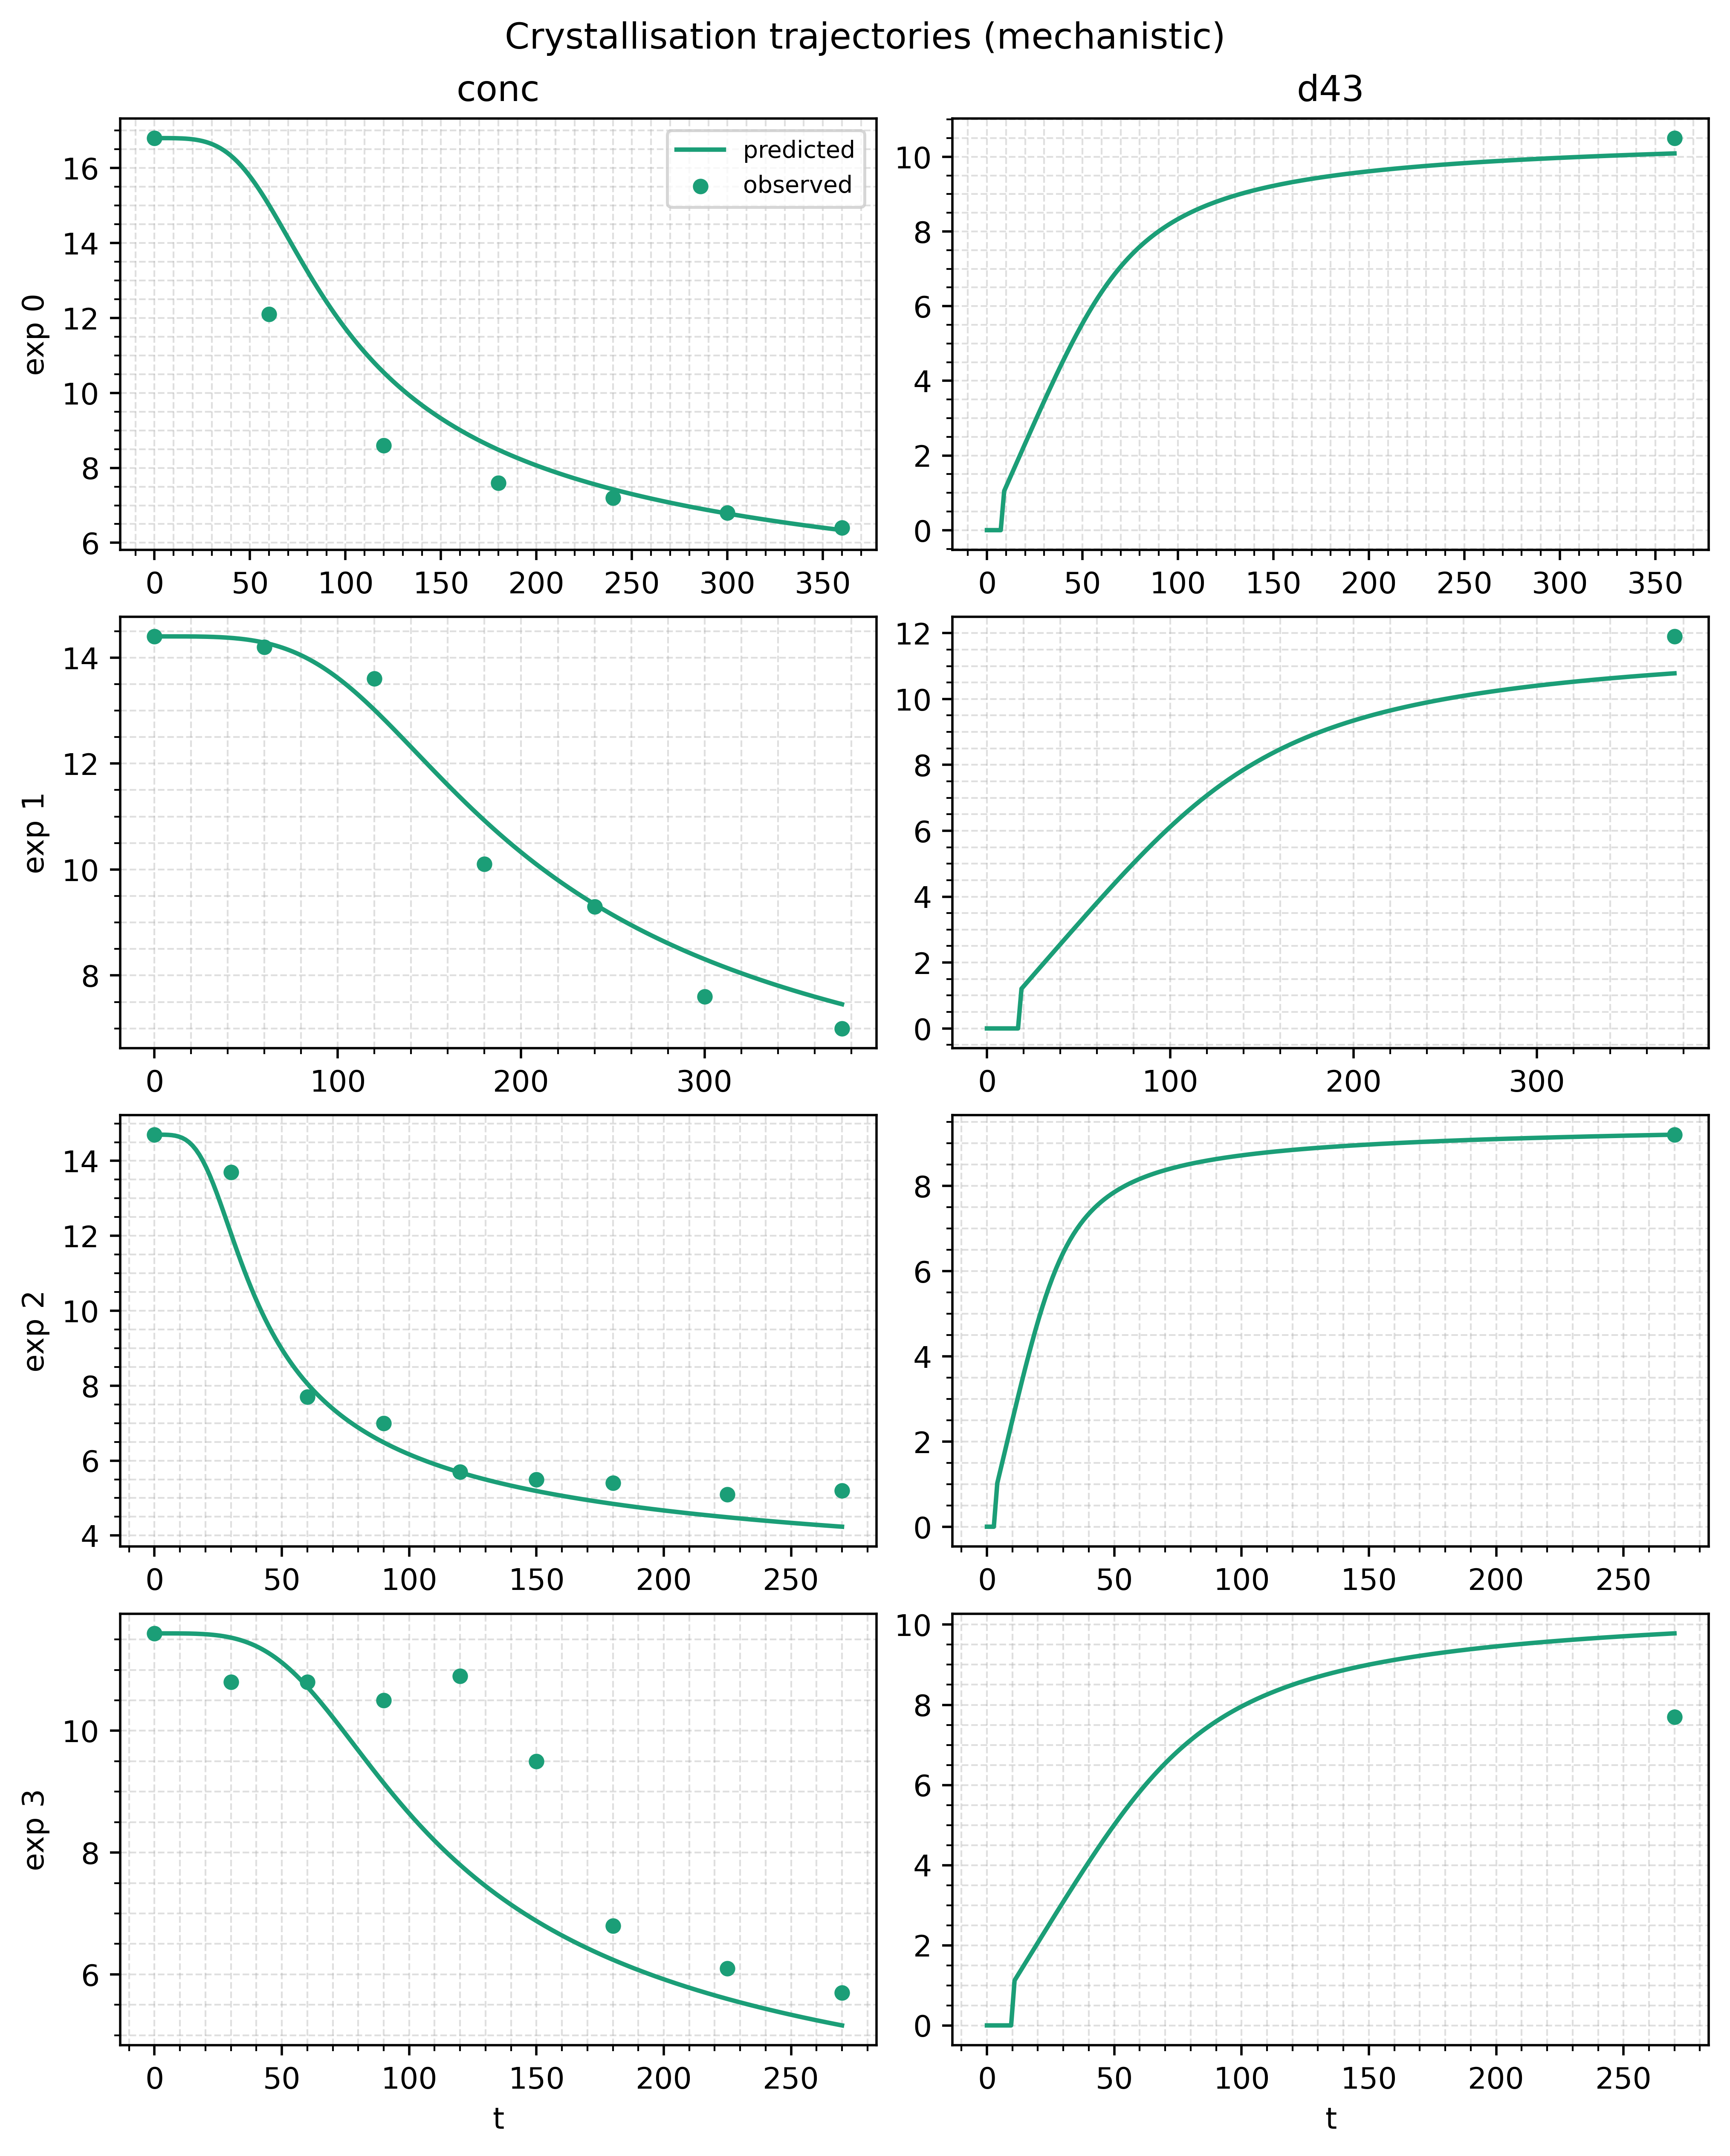
The mechanistic fit gets the shape of each concentration curve but not the timing. Its rates depend only on temperature and supersaturation, with four constants shared by every experiment, so the two 17 °C runs differ only in their starting concentration (14.7 and 11.6). One drops within an hour, the other stays flat for about 150 minutes. CNT and a power law cannot produce that much difference from that change in d43. The hybrid rates face the same constraint but have a free shape in
Things to try
--init uniform_boxor--init warmto compare generation-0 strategies.--population-size 16to see how much a smaller population costs.- Fix
gat 2 by replacing itsParameterwithhm.Constant(2.0), and fit three constants instead of four.